Experimentation Platform That Keeps Your Metrics Honest for Product Teams
An experimentation platform is software that lets product, growth, and marketing teams test changes on real users, measure the results against business metrics, and roll out only what actually works. The payoff is straightforward: fewer bad launches, faster learning cycles, and decisions backed by evidence instead of opinion. Product teams, growth marketers, and data scientists all rely on one to turn guesses into verified outcomes before they hit full traffic.
TL;DR:
- Platforms that support Bayesian or sequential testing provide more flexible result interpretation and faster decision-making compared to traditional frequentist methods.
- Using warehouse-native measurement ensures experiment results align with business dashboards, improving credibility and simplifying data governance.
- Implementing careful instrumentation, starting with one primary metric, and monitoring for sample ratio mismatch are essential steps for trustworthy experiment outcomes.
- Small teams can achieve significant benefits by adopting lightweight, easy-to-integrate tools like Gostellar that support no-code setup and real-time results.
- Building a structured governance system with clear ownership, a shared experiment registry, and documented hypotheses enhances experiment discipline and organizational learning.
Table of Contents
- What Are the Core Components of an Experimentation Platform?
- Why Do Teams Adopt an Experimentation Platform?
- What Features Should You Evaluate in an Experimentation Platform?
- How Does Architecture Affect Experiment Data You Can Trust?
- How Do You Implement an Experimentation Platform Step by Step?
- How Do You Protect the Validity of an Experiment's Results?
- How Should Teams Organize Roles and Governance for Experimentation?
- What Are the Best Practices and Pitfalls in Running Experiments?
- What Does a Practical Experimentation Setup Look Like in Practice?
- Where Is Experimentation Headed, and Should You Build or Buy?
- Get Started With a Lightweight Experimentation Platform
- Sources
- FAQ
What Are the Core Components of an Experimentation Platform?
Every experimentation platform is built from a handful of moving parts that work together, and understanding them helps you spot gaps before you commit budget to one. At the center is an assignment and targeting engine that decides which users see which variant, plus an analytics layer that crunches the results. Around that core sit feature flags for controlling rollout, SDKs for hooking into your codebase, and often a visual editor for people who don't write code.
The no-code visual editor matters more than it sounds. It's the difference between a marketer shipping a headline test in ten minutes and waiting three days for an engineering ticket. But visual editors have limits: they're great for copy, layout, and button changes, and weak for anything that touches backend logic or personalized pricing.
Most platforms support several distinct test types, and picking the wrong one for the job wastes traffic:
- A/B tests compare two versions of a single variable, like a headline or a checkout button color, and are the default starting point for most teams.
- Multivariate tests run multiple variables at once to see which combination performs best, useful when a landing page has several elements worth optimizing together.
- Holdout tests keep a slice of users on the old experience indefinitely, which is how teams measure the cumulative effect of dozens of smaller launches over months.
- Bandit algorithms shift traffic dynamically toward the winning variant in real time, trading statistical rigor for faster exploitation of a likely winner.
- Switchback tests flip the entire population between treatment and control on a schedule, common in marketplaces and logistics where users can't be cleanly split.
Deployment model is the other split worth knowing. Client-side testing runs in the browser and is fastest to set up but adds a flash of unstyled content risk. Server-side (or full-stack) testing runs the logic in your application backend, which is slower to implement but works across web, mobile, and even email or API responses. Firebase A/B Testing is a good example of a mobile-first, server-connected approach that ties directly into app analytics and revenue tracking. Hybrid setups blend both, using client-side for quick UI tests and server-side for anything that touches pricing, algorithms, or backend logic.
Why Do Teams Adopt an Experimentation Platform?
Teams adopt an experimentation platform to stop shipping changes on faith and start shipping them on evidence. A redesign that looks better in a design review can still tank conversion, and the only way to know before it costs you revenue is to test it on a slice of traffic first. Amplitude's guide to experimentation frames this plainly: platforms exist to validate product and marketing changes with real users before a full rollout, which limits the downside of any single bad idea.
The deeper value shows up over time, not in any one test. A single win is nice. A program that runs fifty tests a quarter and retains what it learned from the forty-two that failed is what actually compounds. That's the difference between "we ran an A/B test" and "we run test and learn strategy as an operating model."
Adoption tends to cluster around a few concrete outcomes:
- Risk reduction. Testing a pricing change on 5% of traffic before a full launch limits exposure if the hypothesis is wrong.
- Faster learning cycles. Teams that instrument well can launch, read results, and iterate in days instead of waiting for a quarterly retro to figure out what worked.
- Cross-functional alignment. Product, marketing, and pricing teams stop arguing over opinions when there's a shared, agreed-upon metric that settles the debate.
- Institutional memory. A documented history of what's been tried, and what happened, keeps teams from re-running the same failed idea eighteen months later.
None of this requires enterprise scale. A five-person growth team running a lean platform for marketing experiments gets the same core benefit as a five-hundred-person product org: a faster, cheaper way to find out if an idea is good before betting the business on it.
What Features Should You Evaluate in an Experimentation Platform?
The features that matter most are the ones that determine whether you can trust the numbers, not the ones that look flashiest in a demo. Start with the stat engine. Some platforms default to frequentist significance testing, others offer Bayesian analysis or sequential testing that lets you check results without inflating false positive rates. Know which one you're getting, because it changes how you read every result for the life of the platform.
Metric wiring is the next thing to interrogate. Ask the vendor, or ask yourself if you're building in house, whether the platform's metrics tie back to the same revenue and retention numbers finance and leadership already trust. A platform that reports its own conversion number, disconnected from the metrics in your BI tool, creates a credibility problem the moment two dashboards disagree.
SDK coverage and performance cost deserve equal weight. A heavy script that slows page load can quietly erase the lift a winning variant produces, which is why script size is worth asking about directly rather than assuming it's negligible.
Run through this checklist before you commit to a platform:
- Does the stat engine match how your team wants to interpret results (frequentist, Bayesian, or sequential)?
- Do experiment metrics trace back to the same source-of-truth numbers your finance and leadership teams use?
- What's the script's footprint, and has it been tested for page-speed impact?
- Does it support the SDKs you need for web, mobile, and server-side full-stack tests?
- Does it integrate with your CRM, analytics stack, and data warehouse without custom engineering?
- Are there built-in health checks for sample ratio mismatch and instrumentation errors, and are they automated or manual?
- Can you audit past experiments, including who approved them and what metrics were tracked?
A market mapping of A/B testing tools usefully separates pure experimentation platforms from broader analytics suites and personalization engines. Matching that category to your team's actual skill level, not your ambitions, avoids buying enterprise complexity you'll never fully use.
Pro Tip: *Ask any vendor to show you a failed experiment, not just a winning one.
How Does Architecture Affect Experiment Data You Can Trust?
Architecture decides whether you can trust the numbers a platform hands you, and that makes it the least glamorous, most important choice in the whole stack. Client-side testing, where JavaScript swaps content in the browser, is the fastest to deploy and the easiest for marketers to run without engineering help. The tradeoff is flicker risk, weaker support for backend logic, and a ceiling on what you can test.
Server-side experimentation moves the decision logic into your application backend. It's slower to set up, usually requiring an SDK and a developer's time, but it works uniformly across web, mobile apps, and even backend-only changes like pricing algorithms or search ranking. Most mature programs end up running both models side by side: client-side for quick UI tests marketers own, server-side for anything touching money or core logic.
The bigger architectural shift in recent years is warehouse-native measurement. Instead of a platform calculating results in its own isolated system, a warehouse-native approach runs the experiment analysis as a query directly inside your company's data warehouse, whether that's BigQuery, Snowflake, or Redshift. That single change solves a problem that's plagued experimentation for years: the platform's number and the BI team's number finally agree, because they're calculated from the same underlying data with the same metric definitions.
The practical benefits compound from there:
- Auditability. The same analysts who audit your revenue dashboard can audit your experiment results, using the same query logic.
- Governance. Sensitive data never has to leave your warehouse to reach a third-party analytics layer, which simplifies privacy and compliance reviews.
- Reduced data egress. You're not duplicating event streams across two systems, which cuts both cost and the chance of the two systems drifting apart over time.
- Metric consistency. "Revenue" means the exact same thing in your experiment dashboard as it does in your quarterly board deck.
None of this works without solid telemetry underneath it. Your event pipeline needs to capture the right actions cleanly, tag users consistently across sessions and devices, and feed a warehouse or analytics layer without dropping events under load. A platform that supports full-stack SDKs and feature flags gives engineers a direct hook into that pipeline, while integrations with your CRM and analytics tools keep marketing and product looking at the same underlying truth.
How Do You Implement an Experimentation Platform Step by Step?
Implementation succeeds or fails on the boring parts: clean instrumentation, honest metric selection, and discipline about traffic allocation. Skip any of those and the fanciest platform in the world will still hand you numbers you can't trust. Here's a practical sequence that holds up across most team sizes.
- Define the goal and pick one primary metric. Every experiment needs exactly one metric that decides success, plus two or three secondary metrics for context. Testing five metrics at once and picking whichever one moved is how teams fool themselves.
- Instrument the events before you build the test. Whatever action you're measuring, whether it's a purchase, a signup, or a scroll depth, needs to fire reliably and consistently across the variants you're comparing. This is the single most common source of bad experiment data.
- QA the experiment in a staging environment. Check that both variants render correctly, that tracking fires for each, and that the split actually assigns users the way you expect before a single real visitor sees it.
- Set traffic allocation deliberately. A 50/50 split is standard for most tests, but high-risk changes (pricing, checkout flow) often warrant starting at 5 to 10% of traffic before scaling up.
- Monitor for sample ratio mismatch from day one. If your intended 50/50 split is actually landing at 54/46 after a day, something is broken in assignment or tracking, and every result downstream is now suspect.
- Let the test run to its planned sample size, not to a gut feeling. Calculate the sample size needed for statistical power before you launch, and resist the urge to call it early because the trend looks good on day three.
- Document the result regardless of outcome. A losing test that gets written down saves someone else from re-running it next quarter. A winning test that gets written down becomes institutional knowledge instead of a one-off story.
- Operationalize the win. Roll the winning variant out gradually using feature flags rather than flipping every user over at once, watching for any late-emerging issues as traffic scales.
Spotify's own engineering writeups on building an internal experimentation platform stress starting small and instrumenting carefully before scaling ambition, which is advice that holds whether you're building your own tool or adopting one off the shelf.
Pro Tip: Write the "we will ship this if" and "we will kill this if" thresholds down before the test launches, not after you see the data. Deciding your bar for success after you've seen the numbers is how confirmation bias sneaks into an otherwise rigorous process.
How Do You Protect the Validity of an Experiment's Results?
An experiment's result is only as good as the guardrails protecting it, and the biggest threat isn't a bad idea, it's a broken measurement you don't catch in time. The first rule is picking metrics that mean something to the business, not metrics that are easy to move. Experts at Datadog point out that platforms should prioritize source-of-truth business metrics like revenue and retention over vanity numbers that look good in a slide deck but don't track anything the business actually cares about.
Sample ratio mismatch, or SRM, is the guardrail most teams learn about only after it's already ruined a few weeks of data. SRM happens when the traffic split between variants deviates meaningfully from what you intended, a 48/52 split instead of 50/50, for instance, and it usually signals a bug in assignment logic or a tracking gap rather than random noise. SRM detection is considered a critical health check precisely because an undetected mismatch can quietly invalidate every conclusion drawn from the test.
A short checklist keeps most teams out of trouble:
- Automate SRM checks so a mismatch triggers an alert instead of waiting for someone to notice weeks later.
- Avoid peeking at results daily and calling the test early, as repeated checking before the planned sample size inflates your false positive rate beyond acceptable levels.
- Adjust for multiple comparisons when you're tracking several metrics or running several variants at once, since testing more things raises the odds one looks significant by chance alone.
- Watch performance metrics alongside business metrics. A variant that wins on conversion but adds 400 milliseconds of page load latency, or throws a spike in client-side errors, may be winning for the wrong reason.
That last point gets missed constantly. A test isn't just measuring the metric you care about, it's also measuring whether the change broke something else. Monitoring latency and error rates during a live test the same way you monitor conversion is what separates a mature experimentation program from one that's flying blind on half the picture.
How Should Teams Organize Roles and Governance for Experimentation?
Experimentation scales through structure, not enthusiasm. A team that runs three tests a month with no defined ownership will still be running three tests a month two years later, just with more confusion about who approved what. The fix starts with assigning clear ownership: someone owns the experiment roadmap, someone owns metric definitions, and someone has final say on whether a result is strong enough to ship.
Most mature programs run an experiment registry, essentially a shared log of what's being tested, by whom, against which metric, and what the hypothesis is. This single artifact does double duty: it prevents two teams from accidentally testing conflicting changes on the same audience, and it becomes the institutional memory that keeps a program from repeating its own mistakes.
Governance doesn't need to be heavy to be effective. A few structural habits go a long way:
- Name a metric owner for each source-of-truth number used in experiments, so definitions don't quietly drift between teams over time.
- Require a one-page hypothesis document before launch, stating the expected effect, the primary metric, and the sample size needed.
- Log every experiment in a shared registry, win or lose, so nobody re-runs a test that already has an answer.
- Set an approval threshold for high-risk tests (pricing, checkout, core algorithms) that requires sign-off beyond the person running the test.
Program-level KPIs matter as much as individual test results. Track throughput (how many experiments actually ship per quarter), the win rate (what percentage produce a statistically significant positive result), and, less obviously, how many learnings actually get retained and applied later. A high win rate paired with low retained learning usually means a team is testing timid, low-risk ideas and calling it rigor. The goal isn't a perfect scorecard. It's a program that gets smarter, test over test, instead of relearning the same lesson every year.
What Are the Best Practices and Pitfalls in Running Experiments?
The best experimentation programs share a few unglamorous habits, and the worst ones share the same handful of mistakes. Start simple: a test with one clear variable and clean instrumentation beats an elaborate multivariate setup that nobody can interpret cleanly six weeks later. Complexity is the enemy of trustworthy results, not the sign of a mature program.
Progressive rollout is the practice that separates careful teams from reckless ones. Rather than flipping a change to 100% of users the moment a test looks promising, gradual traffic shifting through feature flags lets you catch problems while the blast radius is still small. If you'd shipped to everyone at once, you own the full fallout.
Documentation is the other habit that quietly compounds. A negative result written down today saves someone six months of redundant work later. Teams that periodically run meta-analyses across past experiments, looking for patterns across dozens of tests rather than judging each one in isolation, tend to spot structural insights that no single test could reveal on its own.
A short list of anti-patterns to watch for:
- Chasing metrics that move easily but mean nothing, like a homepage banner click rate that has no relationship to actual revenue.
- Segmenting results after the fact until something looks significant, which is a textbook way to manufacture a false positive out of noise.
- Running a test for a fixed calendar window instead of the calculated sample size, which under or overpowers results depending on how traffic happened to flow that week.
- Treating a flat or negative result as a failure to hide rather than a data point worth publishing internally.
Good conversion rate optimization practice treats every test, win or loss, as a contribution to a growing body of institutional knowledge, not a one-off bet that either pays off or gets forgotten.
Pro Tip: When a test comes back flat, resist the instinct to immediately slice the data by device, region, or user segment looking for a hidden win. Decide your segmentation rules before launch, or you're just fishing for a story in the noise.
What Does a Practical Experimentation Setup Look Like in Practice?
The tools behind a working experimentation setup are less exotic than most people expect. A lightweight script that doesn't slow page load, a visual editor that a marketer can use without filing an engineering ticket, and analytics that update close to real time cover most of what a small or mid-sized team actually needs day to day. Some platforms combine a lightweight script, a no-code visual editor for setting up tests without a developer, dynamic keyword insertion for personalizing landing pages, and real-time dashboards for reading results as they come in rather than waiting on a batch report.
The pattern holds across team sizes and industries. What separates a program that compounds learning from one that runs a handful of tests and stalls usually comes down to a few practical checkpoints:
- Fast setup removes the biggest adoption barrier. A marketer who can launch a headline test in an afternoon runs more tests than one waiting on a sprint cycle.
- Lightweight scripts protect the metric you're trying to improve. A slow-loading test script can erase the conversion lift a winning variant produced.
- Direct integration with the site builder you already use (WordPress, Shopify, Webflow, Wix, Squarespace, Framer, Bubble) cuts the setup time from days to minutes.
- A data API turns one-off test results into reporting that plugs into whatever dashboard the rest of the business already trusts.
None of this requires a dedicated data science team or a warehouse migration to get started. It requires picking metrics that matter, instrumenting them cleanly, and running enough volume of tests to let the program compound. The teams that get the most out of an experimentation platform, whether they're a five-person startup or a growth team inside a larger company, tend to treat testing as a habit built into the weekly workflow rather than a special project reserved for big launches.
Where Is Experimentation Headed, and Should You Build or Buy?
The two shifts worth watching are warehouse-native measurement and tighter observability integration, and they're related. As more teams demand that experiment metrics match their BI dashboards exactly, running analysis inside the warehouse rather than a black-box layer stops being a nice-to-have and becomes the baseline expectation. Pairing that with performance monitoring, so a test's impact on latency and error rates sits next to its impact on conversion, closes the gap between "did it convert better" and "did it actually work well for users."
AI is going to compress the front end of the process faster than most teams expect. Generating hypotheses, drafting variant copy, and flagging likely-significant results earlier will shrink the time between an idea and a readable result. AI-assisted workflows for marketing teams are already showing up in how experiment ideas get generated and prioritized, and that pace is only going to pick up.
None of that changes the actual bottleneck. Faster idea generation doesn't help you if your measurement isn't trustworthy. If you're uncertain about your team's scale or sophistication, the smarter move is instrumenting cleanly and picking a platform that fits where you are now, not the one built for a scale you might reach someday.
— Juan
Get Started With a Lightweight Experimentation Platform
If everything above sounds right in theory but heavy in practice, that gap is exactly what Gostellar was built to close. Instead of a bulky enterprise tool that needs an engineering sprint to launch a single headline test, Gostellar gives small and mid-sized teams a script under 6 kilobytes, a no-code visual editor, dynamic keyword insertion for personalized landing pages, and real-time dashboards that update as results come in, not after a batch job runs overnight.
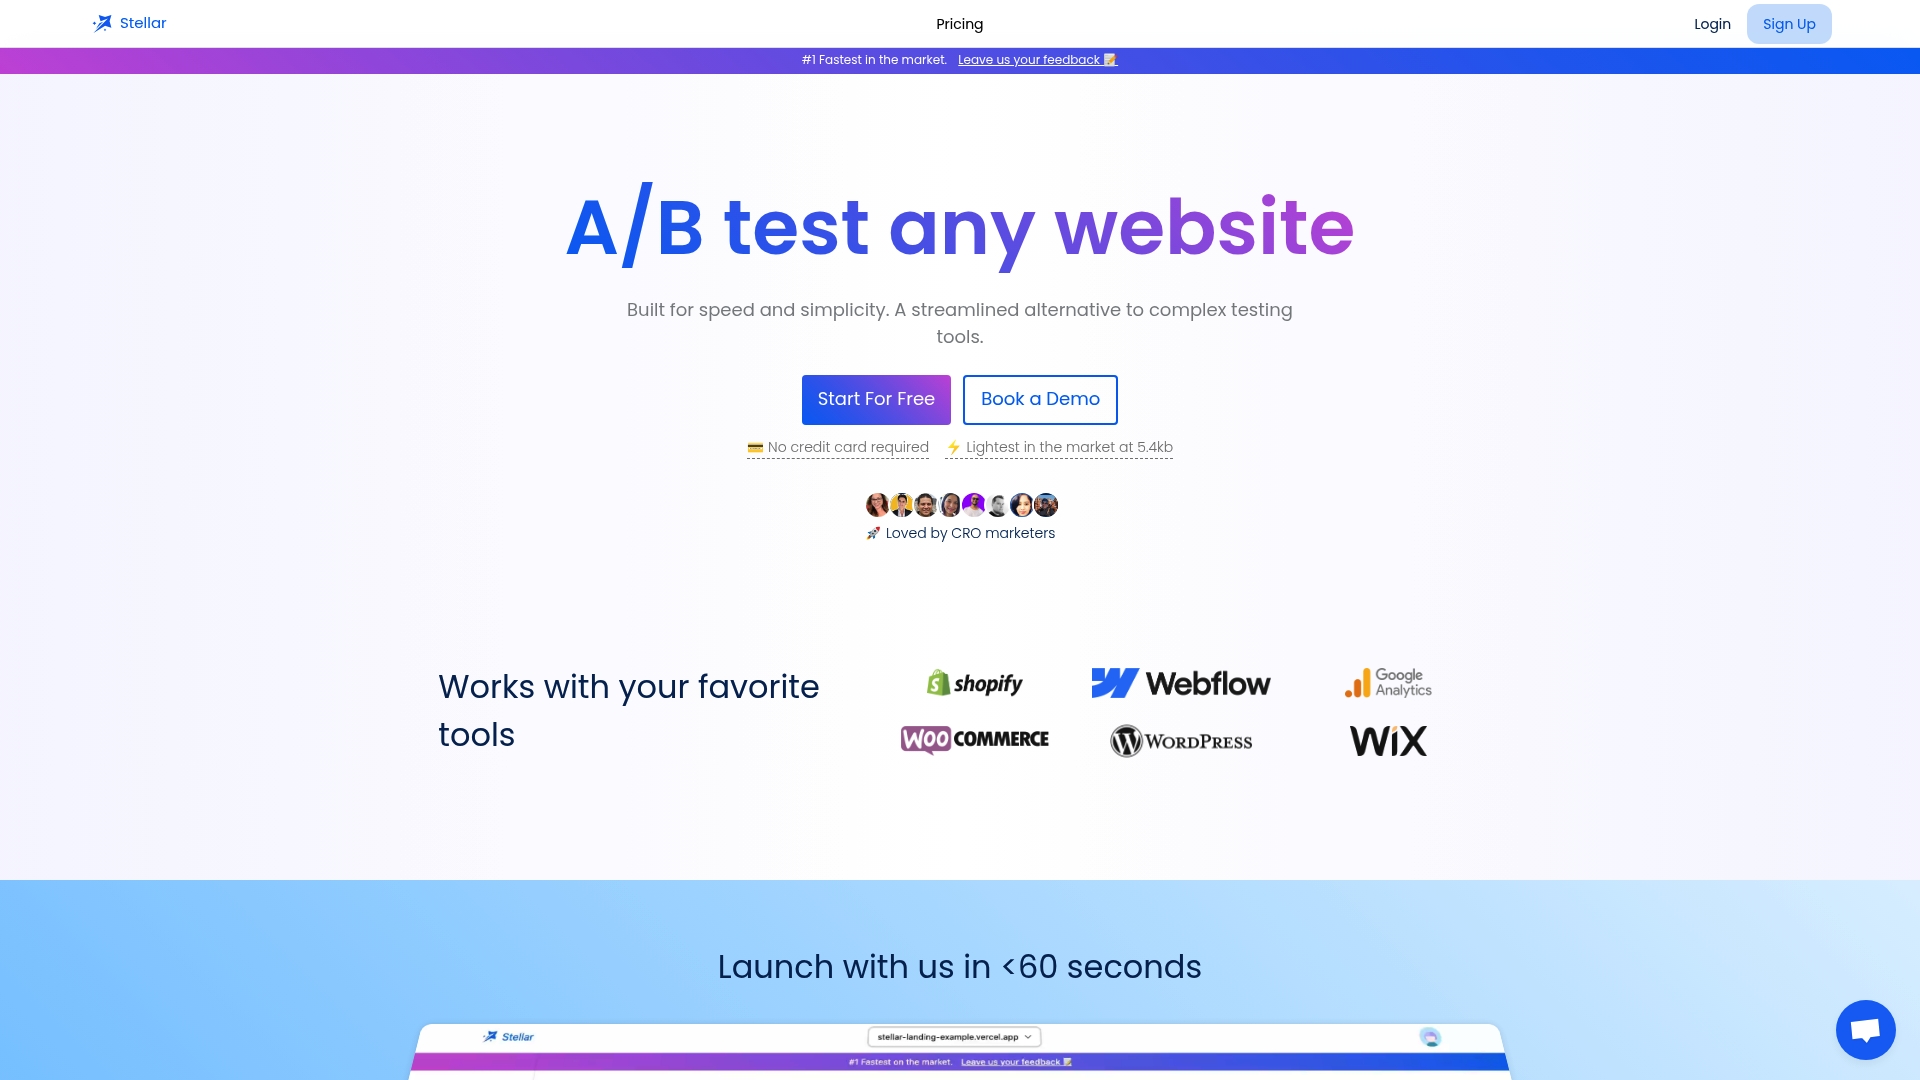
Such platforms may plug directly into popular site builders, enabling setup in minutes rather than a sprint cycle. Many platforms offer free plans for teams with low monthly user counts, with options to scale into paid tiers as traffic grows. If you're ready to move from theory to a live test, start with Stellar and launch your first experiment this week.
Sources
- The Complete Guide to Experimentation Platforms | Amplitude
- Confidence (Spotify) — warehouse-native experimentation concept
- Experiments – Run tests and validate ideas with PostHog
FAQ
What Is an Experimentation Platform?
An experimentation platform is software that lets teams test product, marketing, or pricing changes on a portion of real users and measure the impact against business metrics before rolling the change out to everyone.
What Is an Example of Experimentation in Practice?
A common example is testing two versions of a checkout button, one blue and one green, on a 50/50 traffic split to see which drives more completed purchases, then rolling out the winner using feature flags.
What Does "Experimentation" Mean as a Teaching or Learning Method?
Outside of software, experimentation as a teaching method means learners test a hypothesis through hands-on trial and observation rather than being told the answer directly. The core idea, forming a hypothesis and testing it against real results, is the same principle that underlies A/B testing in product and marketing work.
What Is an Experimentation Program?
An experimentation program is the ongoing organizational practice of running tests systematically, with defined roles, a shared registry of past experiments, and metrics tied to business outcomes, rather than running isolated one-off tests. Mature programs, whether built on a tool like Gostellar or an internal platform, track throughput and win rate alongside individual test results to measure how well they're compounding learning over time.
Recommended
Published: 9/11/2026